[Monolix - PKanalix] Adapt and export a data file as a MonolixSuite formatted data set.
Adapt and export a data file as a MonolixSuite formatted data set.
Usage
formatData(
  dataFile,
  formattedFile,
  headerLines = 1,
  headers,
  linesToExclude = NULL,
  observationSettings = NULL,
  observations = NULL,
  treatmentSettings = NULL,
  treatments = NULL,
  additionalColumns = NULL,
  sheet = NULL
)
Arguments
|
dataFile |
(character) Path to the original data file (csv, xlsx, xlsx, sas7bdat, xpt or txt). Can be absolute or relative to the current working directory. |
|
formattedFile |
(character) Path to the data file that will be exported (must end with the .csv, .txt, .tsv or .xpt extension). |
|
headerLines |
(optional) (integer or vector) Line numbers containing headers (if multiple numbers are given, formatted headers will contain values from all header lines concatenated with the "_" character) - default: 1. |
|
headers |
(list) List of headers or indexes for columns containing information about ID, time, volume (in case of urine data) and sort columns. If the headers are changed by Data Formatting, the original headers should be given.
|
|
linesToExclude |
(optional) (integer or vector) Numbers of lines that should be removed from the data set. |
|
observationSettings |
(optional) (list) List containing settings applied when different observation columns are merged into a single column.
|
|
observations |
(optional) (list) List of lists containing information about different observation types:
|
|
treatmentSettings |
(optional) (list) List containing settings applied to all treatments.
|
|
treatments |
(optional) (list or character) List that can contain lists with information about different treatments or strings with paths to files that contain treatment information.
Path to files that contain treatment information can be just one path (csv, xlsx, xlsx, sas7bdat, xpt or txt, absolute or relative to the current working directory),
or a list of lists with 2 elements to specify for each treatment an xls/xlsx file and sheet in the excel file:
|
|
additionalColumns |
(optional) (character or vector) Path(s) to the file(s) containing additional columns (needs to have the ID column). Accepted formats are csv, xlsx, xlsx, sas7bdat, xpt or txt. It can be just one path, or a list of paths (to use columns from several external files):
or a list of lists with 2 elements to specify an xls/xlsx file and sheet in the excel file:
|
|
sheet |
[optional] (character): Name of the sheet in xlsx/xls file. If not provided, the first sheet is used. |
Details
Data formatting can be performed as in the Data Formatting Tab of Monolix and PKanalix interface. Look at the examples to see how each data formatting demo project could be created with the connectors.
See also
Examples
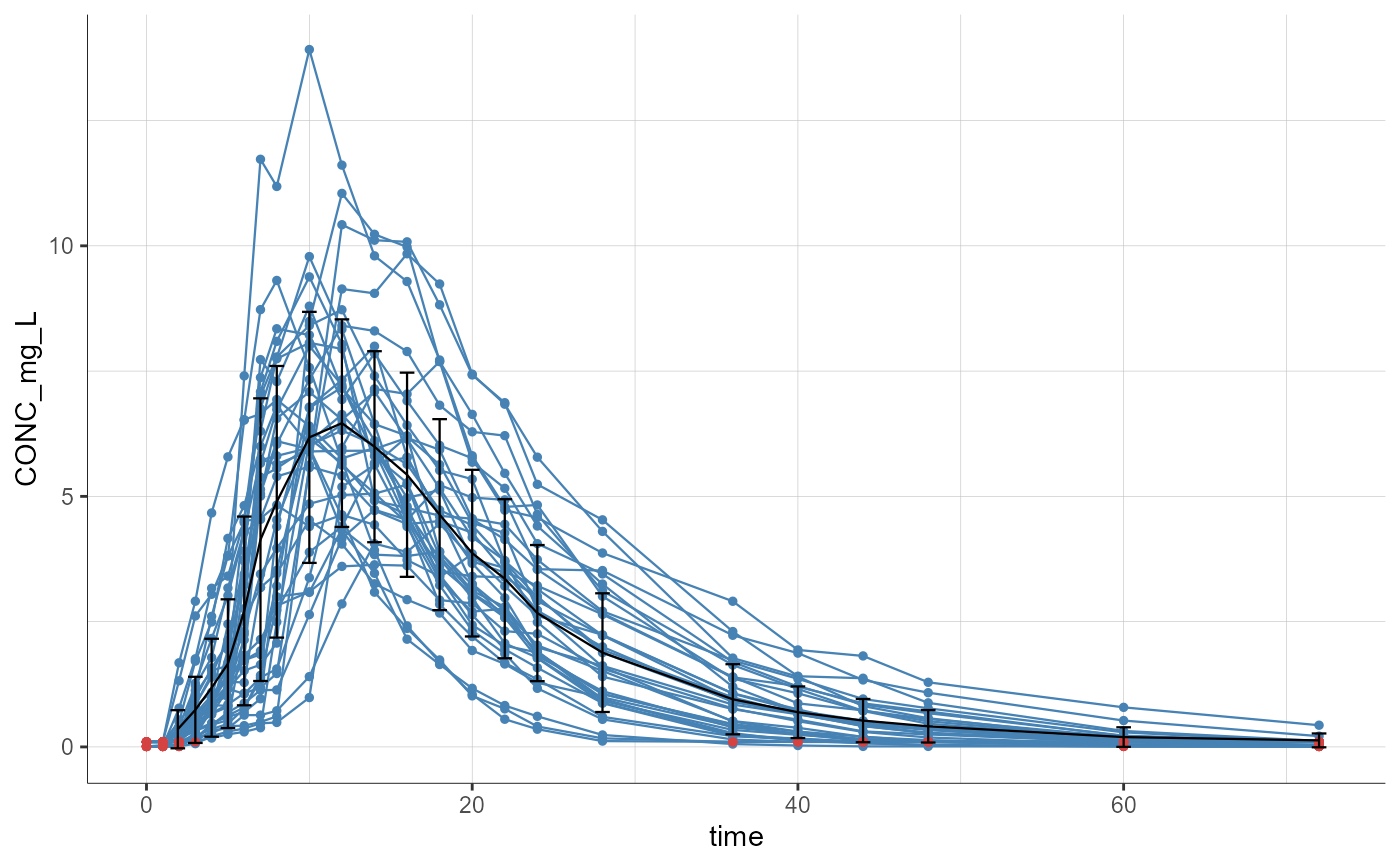
# example: create a new project with a dataset to format:
initializeLixoftConnectors(software = "pkanalix")
FormattedDataPath = tempfile("formatted_data", fileext = ".csv")
formatData(paste0(getDemoPath(),"/0.data_formatting/data/units_BLQ_tags_data.csv"),
           formattedFile = FormattedDataPath,
           headerLines = c(1,2),
           headers = c(id="ID", time="TIME"),
           observations = list(header="CONC",
                               censoring = list(type="interval", tags = c("BLQ"),
                                                limits=list(0,"LLOQ"))),
           treatments = list(times=0, amount=100))
colnames(read.csv(FormattedDataPath)) # to check column names of the generated file and tag them as desired
#>  [1] "ID"        "TIME_h"    "CONC_mg_L" "AGE"       "WT"        "STUDY"
#>  [7] "LLOQ_mg_L" "AMT"       "CENS"      "LIMIT"
newProject(data = list(dataFile = FormattedDataPath, headerTypes = c("id","time","observation","contcov","contcov","catcov","ignore","amount","cens","limit")))
plotObservedData()
#> Warning: No shared levels found between `names(values)` of the manual scale and the
#> data's linetype values.
# demo merge_occ_ParentMetabolite.pkx
formatData(paste0(getDemoPath(),"/0.data_formatting/data/parent_metabolite_data.csv"),
           formattedFile = FormattedDataPath,
           headers = c(id="ID", time="TIME"),
           observations = list(list(header="PARENT",
                                    censoring = list(type="interval", tags = c("BLQ"), limits=list(0,0.01))),
                               list(header="METABOLITE")),
           observationSettings = list(distinguishWithObsId = FALSE),
           treatments = list(times=0, amount="DOSE"))

# demo merge_obsID_ParentMetabolite.pkx
formatData(paste0(getDemoPath(),"/0.data_formatting/data/parent_metabolite_data.csv"),
           formattedFile = FormattedDataPath,
           headers = c(id="ID", time="TIME"),
           observations = list(list(header="PARENT",
                                    censoring = list(type="interval", tags = c("BLQ"), limits=list(0,0.01))),
                               list(header="METABOLITE")),
           treatments = list(times=0, amount="DOSE"))

# demo DoseAndLOQ_byCategory.pkx
formatData(paste0(getDemoPath(),"/0.data_formatting/data/units_BLQ_tags_data.csv"),
           formattedFile = FormattedDataPath,
           headerLines = c(1,2),
           headers = c(id="ID", time="TIME"),
           observations = list(header="CONC",
                               censoring = list(type="interval", tags = c("BLQ"),
                                                limits=list(0,list(category="STUDY",
                                                                   values=list("SD_400mg"=0.01, "SD_500mg"=0.1, "SD_600mg"=0.1))))),
           treatments = list(times=0, amount=list(category="STUDY",
                                                  values=list("SD_400mg"=400, "SD_500mg"=500, "SD_600mg"=600))))

# demo DoseAndLOQ_fromData.pkx
formatData(paste0(getDemoPath(),"/0.data_formatting/data/units_BLQ_tags_data.csv"),
           formattedFile = FormattedDataPath,
           headerLines = c(1,2),
           headers = c(id="ID", time="TIME"),
           observations = list(header="CONC",
                               censoring = list(type="interval", tags = c("BLQ"),
                                                limits=list(0,"LLOQ"))),
           treatments = list(times=0, amount="STUDY"))

# demo DoseAndLOQ_manual.pkx
formatData(paste0(getDemoPath(),"/0.data_formatting/data/units_multiple_BLQ_tags_data.csv"),
           formattedFile = FormattedDataPath,
           headerLines = c(1,2),
           headers = c(id="ID", time="TIME"),
           observations = list(header="CONC",
                               censoring = list(list(type="interval", tags = c("BLQ1"), limits=list(0,0.06)),
                                                list(type="interval", tags = c("BLQ2"), limits=list(0,0.1)))),
           treatments = list(times=0, amount=600))

# demo Urine_LOQinObs.pkx
formatData(paste0(getDemoPath(),"/0.data_formatting/data/urine_LOQinObs_data.csv"),
           formattedFile = FormattedDataPath,
           headers = c(id="ID", start="START TIME", end="END TIME", volume="VOLUME"),
           observations = list(header="CONC",
                               censoring=list(type="LLOQ", tags="<LOQ=1>", limits="CONC")),
           treatments = list(paste0(getDemoPath(),"/0.data_formatting/data/urine_data_doses.csv")))

# demo CreateOcc_AdmIdbyCategory.pkx
formatData(paste0(getDemoPath(),"/0.data_formatting/data/two_formulations_data.csv"),
           formattedFile = FormattedDataPath,
           linesToExclude = 1, headerLines = c(2,3),
           headers = c(id="ID", time="TIME", sort="FORM"),
           observations = list(header="CONC",
                               censoring=list(type="LLOQ", tags="BLQ", limits=0.06)),
           treatments = list(times=0, amount=600, admId=list(category="FORM", values=list("ref"=1,"test"=2))))

# MONOLIX EXAMPLES

initializeLixoftConnectors(software = "monolix")
FormattedDataPath = tempfile("formatted_data")

# demo doseIntervals_as_Occ.mlxtran
formatData(paste0(getDemoPath(),"/0.data_formatting/data/data_multidose.csv"),
           formattedFile = FormattedDataPath,
           headers = c(id="ID", time="TIME"),
           observations = list(header="CONC"),
           treatments = list(times=seq(0,by=12,length=7), amount=40),
           treatmentSettings = list(doseIntervalsAsOccasions = TRUE))

# demo warfarin_PKPDseq_project.mlxtran
formatData(paste0(getDemoPath(),"/0.data_formatting/data/warfarin_data.csv"),
           formattedFile = FormattedDataPath,
           headers = c(id="id", time="time"),
           additionalColumns = paste0(getDemoPath(),"/0.data_formatting/data/warfarinPK_regressors.txt"))